The book “Letters of the 20th Century” · the handwriting primers chapter · July — August 2025
The hidden ChatGPT limit it never mentions itself
A base of 18 editions — ABC books, copybooks and teaching manuals from 1900–1990. An ordinary text PDF weighs hundreds of kilobytes; these, because of hundreds of scans, went over 10 megabytes, and one over 150. Below are two of my posts from that time: what it looked like from the inside and what turned out to be the cause.
In short
What turned out to be the cause
Symptom
After eight to ten PDFs, any new upload silently failed — in any project, even a file under a megabyte. No error message.
Cause
An undocumented limit: the total volume of files in a project is no more than 80 MB, and the threshold applies to the whole account, not to a single project. ChatGPT named the figure only when asked directly.
Workaround
Split the base into groups (books separately, copybooks separately), slice the editions into parts, shrink it down to ten files of ten megabytes. After that the base of 18 editions worked.
Documents
Two posts from that time
My breakdown of the bug and the author’s account of the same two weeks — how it looked from his side. The originals are in Russian.
18 August 2025 · “The ChatGPT bug nobody talks about” — my post on Telegram
The ChatGPT bug nobody talks about Even ChatGPT itself only admits it if you screw with it long and methodically.
Remember I promised to share what I found out while searching for materials for Yuri Gordon’s book about letters?
Everyone who works with projects knows: officially, the Plus subscription lets you upload up to 20 files to a project, with a maximum of 10 files at a time. There are limits on size and format.
In practice it is much harsher. It turns out there is a system bug that is written down nowhere, and even ChatGPT itself won’t own up to it. It only told the truth when I grabbed it by the balls. I was furious. Because it took me a whole week of work to uncover this glitch.
What happened After 8–10 PDF files had been uploaded (regardless of their size), ChatGPT began rejecting any new uploads.
Even if:
- it’s a different project,
- the file weighs less than 1 MB.
So it looks like a glitch, but in fact it is a hidden limit that works not per project but for the whole account/session.
The essence of the bug
- ChatGPT now doesn’t accept PDFs heavier than 10 MB (it used to allow more).
- The limit applies to the account as a whole, not to a specific project.
- If you exceed the threshold (8–10 files), uploading is blocked everywhere: in personal chats, in other projects, and in the memory base.
I tried to trick the system — uploaded PDFs directly into the project chat, asked it to work with them without adding them to memory. But it was all useless: the PDF upload limit applies to the whole account, not just to the project or chat.
The most insidious part The error doesn’t show itself.
You get no message about a limit. The upload just “quietly” fails — as if nothing had happened.
This system bug is described nowhere, and even ChatGPT itself stubbornly plays dumb until you pin it against the wall.
It took me a whole week to get to the truth.
14 July 2025 · “How we taught the double to eat PDFs” — Yuri Gordon’s account, reposted in my channel
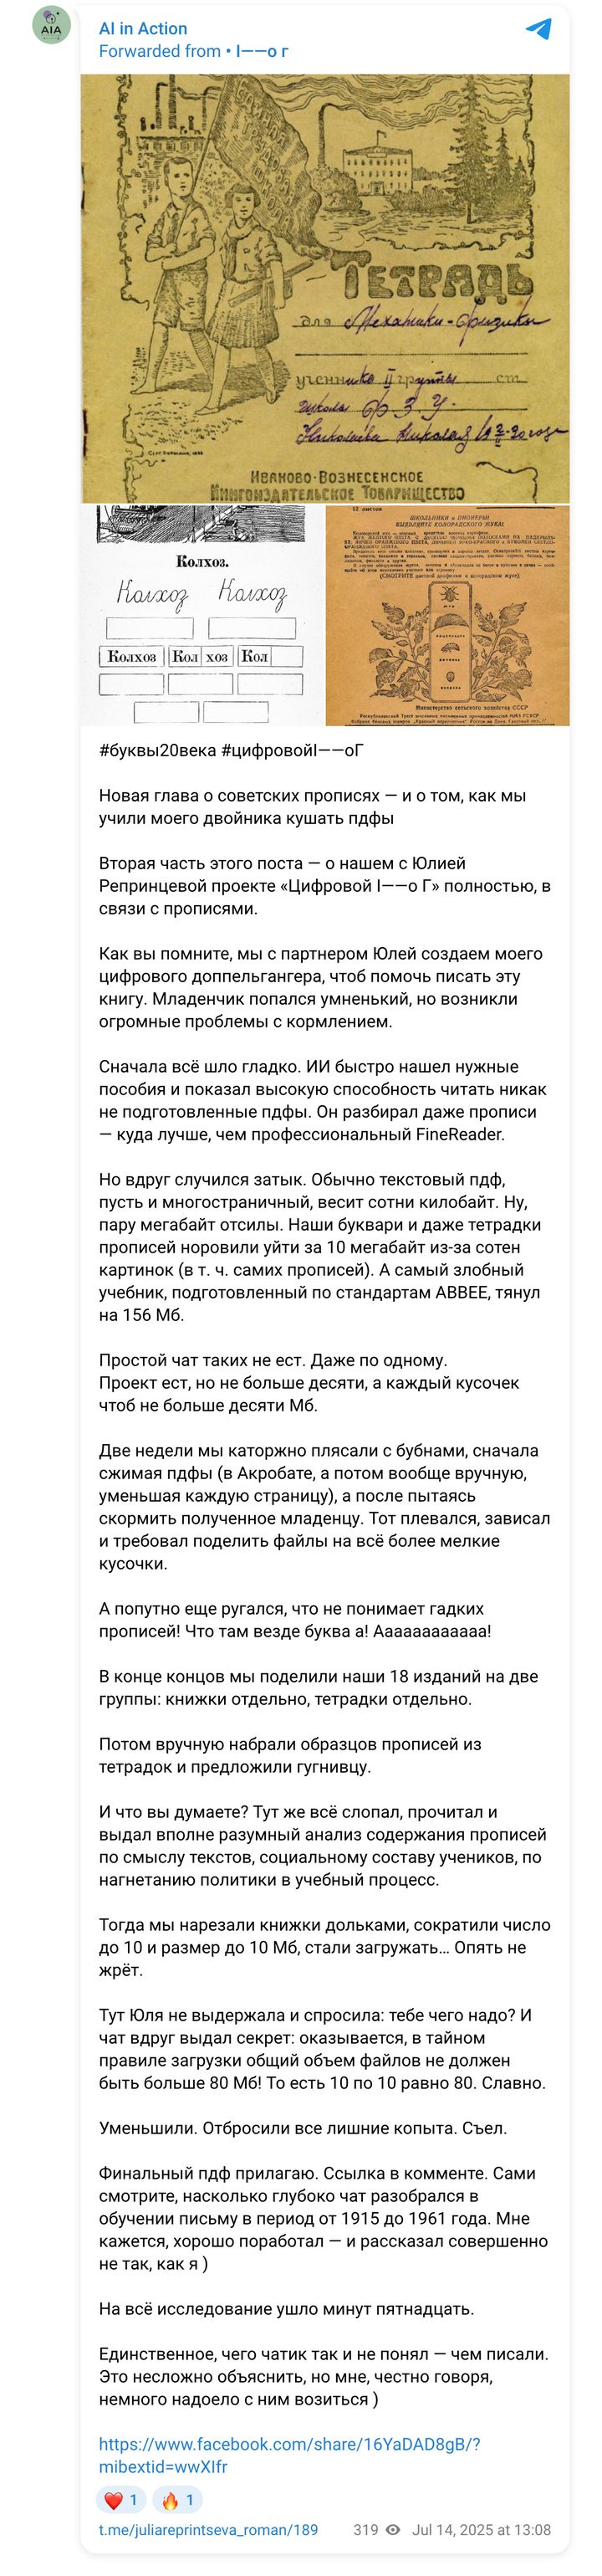
A new chapter on Soviet handwriting primers — and on how we taught my double to eat PDFs
The second part of this post is about Julia Reprintseva’s and my project “Digital YuG” as a whole, in connection with the primers.
As you remember, my partner Julia and I are building my digital doppelgänger to help write this book. The baby turned out to be a clever one, but there were huge problems with feeding.
At first everything went smoothly. The AI quickly found the right manuals and showed a great ability to read PDFs that had not been prepared in any way. It even made out the copybooks — far better than professional FineReader.
But suddenly we hit a snag. A text PDF, even a many-paged one, usually weighs hundreds of kilobytes. A couple of megabytes at most. Our ABC books and even the copybooks kept going over 10 megabytes because of hundreds of images (including the handwriting samples themselves). And the nastiest textbook, prepared to ABBEE standards, came to 156 MB.
A plain chat won’t eat those. Not even one at a time. A project will, but no more than ten, and each piece no bigger than ten MB.
For two weeks we slaved away dancing with tambourines, first compressing the PDFs (in Acrobat, and then entirely by hand, shrinking every page), and then trying to feed the result to the baby. It spat, froze and demanded that the files be cut into ever smaller pieces.
And along the way it also complained that it couldn’t understand the nasty copybooks! That there was the letter “a” everywhere! Aaaaaaaaaaaa!
In the end we split our 18 editions into two groups: books separately, copybooks separately.
Then we typed up samples from the copybooks by hand and offered them to the mumbler.
And what do you think? It gobbled everything up at once, read it and produced a perfectly sensible analysis of the copybooks’ content — the meaning of the texts, the social make-up of the pupils, the growing pressure of politics on the teaching process.
Then we cut the books into slices, reduced the number to 10 and the size to 10 MB, started uploading… It won’t eat again.
At this point Julia lost patience and asked: what do you want? And the chat suddenly let out the secret: it turns out that under a secret upload rule the total volume of files must not exceed 80 MB! So 10 by 10 equals 80. Lovely.
We cut down. Threw off all the extra hooves. It ate.
I attach the final PDF. The link is in the comments. See for yourselves how deeply the chat got to grips with the teaching of writing between 1915 and 1961. I think it did a good job — and told the story quite differently from how I would )
The whole study took about fifteen minutes.
The only thing the chatbot never understood was what people wrote with. It isn’t hard to explain, but, to be honest, I got a bit tired of fussing with it )
Screenshots
How it looked in the channel